
Real Microsoft DP-600 Exam Dumps with Correct 166 Questions and Answers
Valid DP-600 Test Answers & Microsoft DP-600 Exam PDF
NEW QUESTION # 22
You have a Fabric tenant that contains a workspace named Workspace1. Workspace1 contains a data pipeline named Pipeline1 and a lakehouse named Lakehouse1.
You perform the following actions:
- Create a workspace named Workspace2.
- Create a deployment pipeline named DeployPipeline1 that will deploy
items from Workspace1 to Workspace2.
- Add a folder named Folder1 to Workspace1.
- Move Lakehouse1 to Folder1.
- Run DeployPipeline1.
Which structure will Workspace2 have when DeployPipeline1 is complete?
- A. \Pipeline1
\Lakehouse1 - B. \Folder1\Pipeline1
\Folder1\Lakehouse1 - C. \Pipeline1
\Folder1\Lakehouse1 - D. \Folder1\Lakehouse1
Answer: D
NEW QUESTION # 23
You have a Fabric notebook that has the Python code and output shown in the following exhibit.

Which type of analytics are you performing?
- A. diagnostic
- B. descriptive
- C. prescriptive
- D. predictive
Answer: B
Explanation:
The Python code and output shown in the exhibit display a histogram, which is a representation of the distribution of data. This kind of analysis is descriptive analytics, which is used to describe or summarize the features of a dataset. Descriptive analytics answers the question of "what has happened" by providing insight into past data through tools such as mean, median, mode, standard deviation, and graphical representations like histograms.
References: Descriptive analytics and the use of histograms as a way to visualize data distribution are basic concepts in data analysis, often covered in introductory analytics and Python programming resources.
NEW QUESTION # 24
You have a Microsoft Power BI semantic model.
You need to identify any surrogate key columns in the model that have the Summarize By property set to a value other than to None. The solution must minimize effort.
What should you use?
- A. Model explorer in Microsoft Power BI Desktop
- B. Model view in Microsoft Power BI Desktop
- C. Best Practice Analyzer in Tabular Editor
- D. DAX Formatter in DAX Studio
Answer: C
Explanation:
Best Practice Analyzer should be able to identify these with some rules.
NEW QUESTION # 25
You need to ensure that Contoso can use version control to meet the data analytics requirements and the general requirements. What should you do?
- A. Modify the settings of the Research division workspaces to use an Azure Repos repository.
- B. Store all the semantic models and reports in Microsoft OneDrive.
- C. Store all the semantic models and reports in Data Lake Gen2 storage.
- D. Modify the settings of the Research workspaces to use a GitHub repository.
Answer: A
Explanation:
You need to ensure that Contoso can use version control to meet the data analytics requirements and the general requirements.
Requirement: "All the semantic models and reports for the Research division must use version control that s upports branching." Fabric supports Git integration (Azure Repos or GitHub) for semantic models and reports.
Storing in Data Lake Gen2 or OneDrive does not provide version control with branching.
The correct action is to integrate workspaces with a Git repository.
Modify the settings of the Research division workspaces to use an Azure Repos repository.
NEW QUESTION # 26
You have a Fabric workspace named Workspacel that contains a lakehouse named Lakehousel. Lakehousel contains a table named Tablel. Table 1 contains the following data.
You need to perform the following actions:
* Load the data from Table! into a star schema.
* Create a product dimension table named DimProduct and a fact table named FactSales.
Which three columns should you include in DimProduct?
- A. Date, ProductID, andTransactionlD.
- B. ProductName, SalesAmount, andTransactionlD
- C. ProductColor, ProductID, and ProductName.
- D. ProductID, ProductName, and SalesAmount
Answer: C
Explanation:
Topic 2, Litware. Inc. Case Study
Overview
Litware. Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
litware has been using a Microsoft Power Bl tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Fabric Environment
Litware has data that must be analyzed as shown in the following table.
The Product data contains a single table and the following columns.
The customer satisfaction data contains the following tables:
* Survey
* Question
* Response
For each survey submitted, the following occurs:
* One row is added to the Survey table.
* One row is added to the Response table for each question in the survey.
The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Litware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity.
The following three workspaces will be created:
* AnalyticsPOC: Will contain the data store, semantic models, reports, pipelines, dataflows, and notebooks used to populate the data store
* DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate Onelake
* DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
* A data store (type to be decided)
* A custom semantic model
* A default semantic model
* Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
* Read access by using T-SQL or Python
* Semi-structured and unstructured data
* Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model.
The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model.
The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SQL queries and in the default semantic model. The following logic must be used:
* List prices that are less than or equal to 50 are in the low pricing group.
* List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
* List pnces that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC. Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
* Fabric administrators will be the workspace administrators.
* The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
* The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
* The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook.
* The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power Bl reports by using the semantic models created by the analytics engineers.
* The date dimension must be available to all users of the data store.
* The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
* FabricAdmins: Fabric administrators
* AnalyticsTeam: All the members of the analytics team
* DataAnalysts: The data analysts on the analytics team
* DataScientists: The data scientists on the analytics team
* Data Engineers: The data engineers on the analytics team
* Analytics Engineers: The analytics engineers on the analytics team
Report Requirements
The data analysis must create a customer satisfaction report that meets the following requirements:
* Enables a user to select a product to filter customer survey responses to only those who have purchased that product
* Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected date
* Shows data as soon as the data is updated in the data store
* Ensures that the report and the semantic model only contain data from the current and previous year
* Ensures that the report respects any table-level security specified in the source data store
* Minimizes the execution time of report queries
NEW QUESTION # 27
You have a Fabric tenant that contains a lakehouse named Lakehouse1
Readings from 100 loT devices are appended to a Delta table in Lakehouse1. Each set of readings is approximately 25 KB. Approximately 10 GB of data is received daily.
All the table and SparkSession settings are set to the default.
You discover that queries are slow to execute. In addition, the lakehouse storage contains data and log files that are no longer used.
You need to remove the files that are no longer used and combine small files into larger files with a target size of 1 GB per file.
What should you do? To answer, drag the appropriate actions to the correct requirements. Each action may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
* Remove the files: Run the VACUUM command on a schedule.
* Combine the files: Set the optimizeWrite table setting. or Run the OPTIMIZE command on a schedule.
To remove files that are no longer used, the VACUUM command is used in Delta Lake to clean up invalid files from a table. To combine smaller files into larger ones, you can either set the optimizeWrite setting to combine files during write operations or use the OPTIMIZE command, which is a Delta Lake operation used to compact small files into larger ones.
NEW QUESTION # 28
Hotspot Question
You have a Fabric tenant that contains a warehouse named Warehouse1. Warehouse1 contains three schemas named schemaA, schemaB, and schemaC.
You need to ensure that a user named User1 can truncate tables in schemaA only.
How should you complete the T-SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 29
You have a Fabric tenant that contains customer churn data stored as Parquet files in OneLake. The data contains details about customer demographics and product usage.
You create a Fabric notebook to read the data into a Spark DataFrame. You then create column charts in the notebook that show the distribution of retained customers as compared to lost customers based on geography, the number of products purchased, age. and customer tenure.
Which type of analytics are you performing?
- A. diagnostic
- B. descriptive
- C. prescriptive
- D. predictive
Answer: B
Explanation:
The charts in the Fabric notebook are summarizing customer churn data (retained vs lost customers) across dimensions such as geography, products purchased, age, and tenure. This is describing "what has happened" in the data.
Descriptive analytics summarizes and visualizes historical data.
Diagnostic analytics explains "why" events occurred.
Predictive analytics forecasts future outcomes.
Prescriptive analytics recommends actions.
Since only distributions are being shown, this is descriptive analytics.
References:
Microsoft Learn - Types of Analytics in Fabric
Descriptive Analytics concepts
NEW QUESTION # 30
You are implementing a medallion architecture in a single Fabric workspace.
You have a lakehouse that contains the 8ronze and Silver layers and a warehouse that contains the Gold layer.
You create the items required to populate the layers as shown in the following table.
You need to ensure that the layers are populated daily in sequential order such that Silver is populated only after Bronze is complete, and Gold is populated only after Silver is complete. The solution must minimize development effort and complexity.
What should you use to execute each set of items? To answer, drag the appropriate options to the correct items. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
To execute each set of items in sequential order with minimized development effort and complexity, you should use the following options:
* Orchestration pipeline: Use a pipeline with an Invoke pipeline activity. This allows for orchestrating and scheduling the execution of other pipelines, ensuring they run in the correct sequence.
* Bronze layer: Implement a pipeline Copy activity. This aligns with the table indicating that the Bronze layer uses pipelines with Copy activities for data integration.
* Silver layer: Implement a pipeline Dataflow activity. The table specifies that Dataflows are used for the Silver layer.
* Gold layer: Implement a pipeline Stored procedure activity. Stored procedures are specified for the Gold layer according to the table.
NEW QUESTION # 31
You have a Microsoft Power BI project that contains a file named definition.pbir. definition.pbir contains the following JSON.
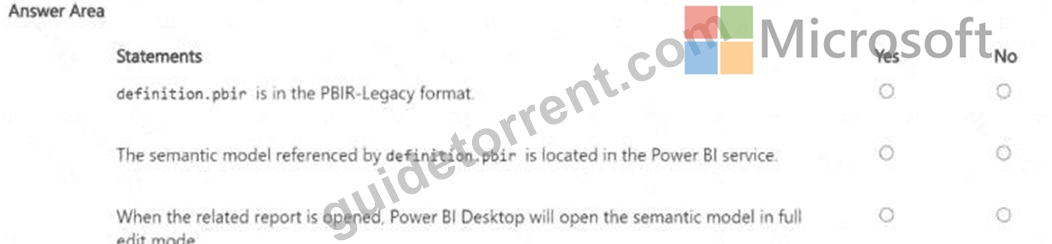
Answer:
Explanation: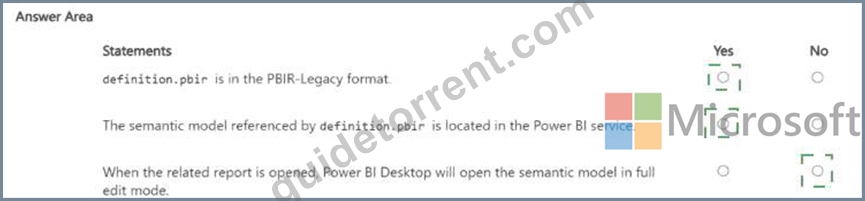
Explanation: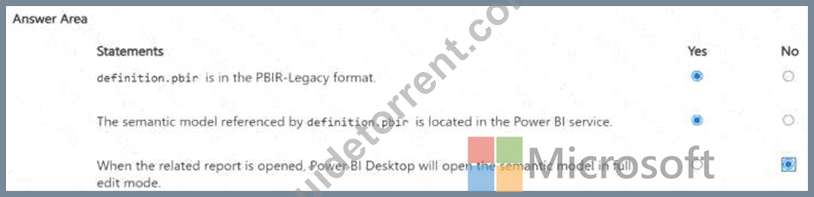
NEW QUESTION # 32
You have a Fabric tenant named Tenant1 that contains a lakehouse named Lakehouse1.
You need to add data to Lakehouse1 from a CSV file in an Azure Storage account outside of Fabric. The solution must minimize development effort.
What should you use to add the data?
- A. copy job
- B. Dataflow Gen2
- C. shortcut
- D. pipeline
Answer: C
NEW QUESTION # 33
You have a Fabric tenant.
You are creating a Fabric Data Factory pipeline.
You have a stored procedure that returns the number of active customers and their average sales for the current month.
You need to add an activity that will execute the stored procedure in a warehouse. The returned values must be available to the downstream activities of the pipeline.
Which type of activity should you add?
- A. Copy data
- B. Append variable
- C. KQL
- D. Lookup
Answer: D
Explanation:
Lookup activity reads and returns the content of a configuration file or table. It also returns the result of executing a query or stored procedure. The output can be a singleton value or an array of attributes, which can be consumed in a subsequent copy, transformation, or control flow activities like ForEach activity.
https://learn.microsoft.com/en-us/azure/data-factory/control-flow-lookup-activity
NEW QUESTION # 34
You have a Fabric tenant that contains a complex semantic model. The model is based on a star schema and contains many tables, including a fact table named Sales.
You need to visualize a diagram of the model. The diagram must contain only the Sales table and related tables.
What should you use from Microsoft Power BI Desktop?
- A. Data view
- B. data categories
- C. Model view
- D. DAX query view
Answer: C
Explanation:
The Model view in Microsoft Power BI Desktop allows you to visualize the relationships between tables in a semantic model. It displays a diagram of the data model, where you can focus on specific tables, such as the Sales fact table and its related tables, by arranging or filtering the view. This is the ideal tool for analyzing the structure of a star schema and understanding table relationships.
NEW QUESTION # 35
You have a Fabric tenant that contains a warehouse named Warehouse1. Warehouse1 contains three schemas named schemaA, schemaB. and schemaC You need to ensure that a user named User1 can truncate tables in schemaA only.
How should you complete the T-SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.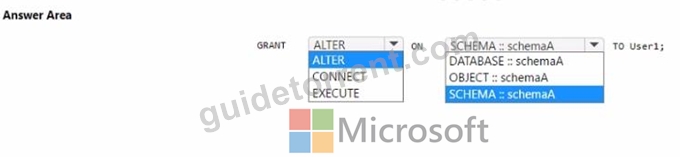
Answer:
Explanation:
NEW QUESTION # 36
You have a Fabric warehouse that contains the following data.
The data has the following characteristics:
* Each customer is assigned a unique CustomerlD value.
* Each customer is associated to a single SalesRegion value.
* Each customer is associated to a single CustomerAddress value.
* The Customer table contains 5 million rows.
* All foreign key values are non-null.
You need to create a view to denormalize the data into a customer dimension that contains one row per distinct CustomerlD value. The solution must minimize query processing time and resources.
How should you complete the T-SQL statement? To answer, select the appropriate options in the answer area.
Answer:
Explanation:
Explanation:
NEW QUESTION # 37
You have a Fabric tenant that contains a workspace named Workspace1. Workspace1 uses Pro license mode and contains a semantic model named Model1. You need to ensure that Modell supports XMLA connections.
Which setting should you modify?
- A. Enforce strict access control for all data connection types
- B. Enable Cache for Shortcuts
- C. Users can edit data models in the Power B1 service
- D. License mode
Answer: D
Explanation:
XMLA endpoint connectivity (read/write) requires the workspace to be in Fabric (Premium) capacity.
A Pro workspace does not support XMLA connections.
Therefore, to enable XMLA for Model1, you must change the License mode from Pro to Premium/Fabric.
Correct answer: B
Reference: XMLA endpoints in Power BI/Fabric
NEW QUESTION # 38
You have a Fabric tenant that contains a lakehouse.
You are using a Fabric notebook to save a large DataFrame by using the following code.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
The results will form a hierarchy of folders for each partition key. - Yes The resulting file partitions can be read in parallel across multiple nodes. - Yes The resulting file partitions will use file compression. - No Partitioning data by columns such as year, month, and day, as shown in the DataFrame write operation, organizes the output into a directory hierarchy that reflects the partitioning structure. This organization can improve the performance of read operations, as queries that filter by the partitioned columns can scan only the relevant directories. Moreover, partitioning facilitates parallelism because each partition can be processed independently across different nodes in a distributed system like Spark. However, the code snippet provided does not explicitly specify that file compression should be used, so we cannot assume that the output will be compressed without additional context.
References =
DataFrame write partitionBy
Apache Spark optimization with partitioning
NEW QUESTION # 39
......
Microsoft DP-600 Exam Syllabus Topics:
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
DP-600 Exam Questions and Valid PMP Dumps PDF: https://lead2pass.guidetorrent.com/DP-600-dumps-questions.html